Updated 16 Oct 2026 · 36 offers checked
Where to rent an A100 SXM at the cheapest price
We read every A100 SXM 80 GB offer we could find on the provider's own page, worked out what each hour includes and what a month really costs, and measured the ageing card against the H100 per finished job rather than per hour.
The short answer, 16 Oct 2026
- $0.95/hrCheapest A100 SXM machine on demand. GPUBank at $0.95 an hour, billed per second, with 16 vCPU, 125 GB of RAM, a 1 TB NVMe disk, a public IPv4 address and all traffic in the price; $0.76 reserved for a week or a month and about $0.59 effective after the bonus on a $1,000 top-up1. The next managed offers were CloudRift at $1.05 and Thunder Compute at $1.0923.
- $0.53/hrCheapest interruptible hour. A Vast.ai bid of about $0.53 on an Iowa host, the lowest minimum bid among the live A100 SXM4 80 GB offers on 16 October 2026; a higher bidder can stop it at any time and storage is billed on top. GPUBank's interruptible tier, with five minutes of notice, costs $0.5741.
- $0.94/hrCheapest marketplace listing. The same Iowa host on demand at $0.937 with 32 CPU cores, before its storage at about $0.33 per GB-month and its bandwidth; the cheaper A100 SXM4 rows that day were all 40 GB cards4.
The A100 SXM is six years old and still one of the most rented 80 GB GPUs there is. That longevity has produced an odd market: the same card is listed at $0.94 an hour by a marketplace host in Iowa, at $1.05 to $1.79 by specialised clouds that sell one card with its CPU, memory and disk, at $2.79 per GPU by Lambda in an eight-GPU instance, and at $3.43 to $5.07 by the large clouds425678. GetDeploying, which tracks 39 priced providers, put the median on-demand A100 hour at $1.88 on 15 October 2026, a figure that mixes 40 GB, 80 GB, PCIe and SXM rows and therefore reads better as a market temperature than as the price of this exact card9.
The spread is not noise. Each price buys a different machine, a different meter, a different minimum unit and a different promise about what happens when a host breaks, and many listings that say only "A100 80GB" never state whether the card is the SXM module or the PCIe board. This page compares like with like, keeps the 40 GB and PCIe versions apart, and then asks the question that matters for an ageing card: whether it is still cheaper per finished job than an H100 that costs about twice as much per hour. It is published by GPUBank, a GPU cloud run by GPU Compute OÜ in Tallinn and one of the providers compared, so read our own entry with that in mind: it is priced on the same terms as every other offer, and the text says where a marketplace host, a spot bid or a faster card beats it.
01 / Still cheap, per job?
An ageing card that is still cheap
The A100's price history is less of a straight decline than its age suggests. The large clouds set the ceiling and have barely moved it: Azure's ND96amsr A100 v4 has listed at $4.10 per GPU since December 2021, and AWS's p4de fell from $5.12 per GPU in 2022 to $3.43 only after a price cut in June 2025202726. The specialised clouds did not fall in a line either: Lambda's eight-GPU A100 80 GB went from $1.50 in May 2023 to $1.79 in 2024 and 2025 and costs $2.79 today, and Runpod's Secure Cloud SXM went from $1.84 in 2023 to $2.29 in 2024 and back to $1.794041642435. What did fall is the floor: in October 2026 a whole machine costs $0.95 and a marketplace host $0.94, while the card itself has gone from roughly $10,000 new in 2023 to about $5,000 in realised used sales144435.
Renting one A100 80 GB, 2021 to 2026Large clouds, per GPU of 8Lambda, 8 GPUsRunpod, 1 GPUVast.aiGPUBank
USD per GPU-hour, on demand. Every point on the chart:
- Dec 2021$4.10Azure ND96amsr A100 v4, list price per GPU (8x SXM4 80 GB), unchanged since20
- Aug 2022$5.12AWS p4de.24xlarge on demand, $40.96 for 8x A100 80 GB27
- May 2023$1.50Lambda 8x A100 80 GB on demand40
- Jul 2023$1.84Runpod Secure Cloud, 1x A100 SXM 80 GB42
- Jun 2024$2.29Runpod Secure Cloud, 1x A100 SXM 80 GB43
- Mar 2025$1.79Lambda 8x A100 SXM 80 GB on demand41
- Oct 2026$3.43AWS p4de.24xlarge on demand, after the June 2025 cut7
- Oct 2026$2.79Lambda 8x A100 SXM 80 GB on demand6
- Oct 2026$0.937Vast.ai cheapest A100 SXM4 80 GB listing, on demand4
- Oct 2026$0.95GPUBank A100 SXM on demand, whole machine1
Buying one, 2020 to 20268-GPU system, per GPUOne module, new then sold usedUsed module, quoted or asked
USD per GPU; whole systems are divided by eight. Every point on the chart:
- May 2020$24,875NVIDIA DGX A100 launch price (8x A100 40 GB), $199,000 for eight45
- Feb 2023$10,000A100 chip, "roughly $10,000" (CNBC, variant not stated)44
- Mar 2026$7,000Used A100 SXM 80 GB, $5,000 to $9,000 (Jarvislabs guide)37
- Aug 2026$5,050Used A100 SXM4 80 GB, realised sales over 12 months, down about 35 percent, range $4,700 to $5,40035
- Sep 2026$9,925Used A100 SXM4 80 GB, median US asking price, 4 listings, range $8,300 to $12,20036
- Oct 2026$11,900Used HGX A100 8x 80 GB node, valuation, $95,200 for eight34
Cheaper per hour, but not always per job
Cheap per hour is not the same as cheap per job, and the measured ratios decide which card to rent. On GPUBank the H100 SXM costs 1.95 times the A100's rate, so the A100 stays the sensible choice wherever the H100 is less than about twice as fast: long-sequence and memory-bound inference, ResNet-style training, BF16 stacks that cannot use FP8, QLoRA runs that spend real time loading data and writing checkpoints, notebooks that sit idle, and any session billed while you think. The H100 is cheaper per job on short, compute-heavy work and on anything that can run FP8, as the BERT result shows, and its advantage grows with concurrency. The practical test costs little: run your own job for half an hour on each card at per-second rates, divide the price by the throughput you measured, and keep the cheaper card.
A100 SXM$0.95/GPU-hr
H100 SXM$1.85/GPU-hr
The H100 must be this much faster to cost less1.95×
BERT-large training, 8 GPUs (MLPerf Training v2.1)30
H100 measured 2.65× faster, needs 1.95×
ResNet-50 training, 8 GPUs (MLPerf Training v2.1)30
H100 measured 1.95× faster, needs 1.95×
Llama 3.1 8B, 1,000 in and 1,000 out tokens, 1 GPU (E2E, TensorRT-LLM)33
H100 measured 1.98× faster, needs 1.95×
Cost of each run at GPUBank on-demand rates: minutes to target × GPUs × price per GPU-hour, or price per GPU-hour divided by tokens per hour for serving. A gap under 5 percent is called a tie. The meter marks the speed-up the H100 needs (1.95×, its price over the A100's) and the speed-up measured30331.
02 / The card
What the A100 SXM is, and who still rents it
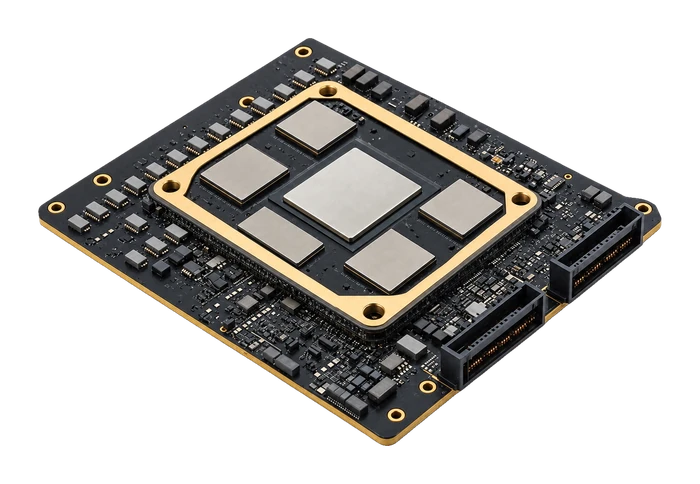
The A100 SXM4 80 GB is NVIDIA's Ampere data-centre accelerator in its mezzanine form, a module that sits on an HGX baseboard rather than in a PCIe slot. NVIDIA's specification gives it 80 GB of HBM2e at 2,039 GB/s, NVLink at 600 GB/s between the cards of a board, a 400 W thermal design power in the standard configuration and up to seven MIG instances of 10 GB each, with 312 TFLOPS of dense BF16 and FP16 tensor throughput10. It has no FP8, which is the main architectural gap against Hopper, where FP8 roughly doubles tensor throughput again for the models and frameworks that use it. The first A100s shipped in 2020 with 40 GB of memory, the 80 GB SXM module followed late that year and the 80 GB PCIe card later still; the PCIe board has a lower power limit, slightly less bandwidth and, in most servers, no full NVLink mesh, so the three versions are treated as different products in every price comparison on this page.
The variant problem is real when shopping. AWS's p4d.24xlarge carries eight 40 GB cards and only the p4de.24xlarge carries 80 GB, Lambda's single-GPU A100 is a 40 GB card while its 80 GB SXM comes only in an eight-GPU instance, and Thunder Compute, Jarvislabs, Koyeb and Modal list an "A100 80GB" without stating the form factor1163121314. The people who still rent this card are mostly fine-tuning 7B to 70B models with LoRA or QLoRA, running batch inference in BF16 on stacks that do not use FP8, keeping Ampere-era CUDA code alive, or splitting one card into MIG slices for several small services. The QLoRA authors fine-tuned a 65B model on a single 48 GB GPU, so 80 GB leaves room for a 70B model at 4-bit with a useful context and batch size15.
03 / The price ladder
How to read the A100 SXM market
A managed cloud sells a fixed machine, the GPU with its vCPUs, memory and local disk, at one hourly price that may or may not include the public IP, the persistent storage and the traffic. For the A100 SXM that group runs from GPUBank's $0.95 through CloudRift at $1.05, Thunder Compute at $1.09, Beam at $1.36, Massed Compute at $1.38, Jarvislabs at $1.49 and Hyperstack at $1.60 to Runpod Secure Cloud at $1.79 and Verda at $1.99612316171218519. A peer-to-peer marketplace lets independent hosts post their own GPU price and bills storage and bandwidth as separate lines set by each host, which is why Vast.ai's $0.937 and a managed $0.95 are not two prices for the same product even though they sit a cent apart4.
The other three kinds of offer trade something away for the price. Spot or interruptible capacity can be taken back: on Vast.ai you bid and can be outbid, GPUBank gives five minutes of notice and stops rather than deletes the machine, and on Azure the eight-GPU ND96amsr A100 v4 spot instance is evicted when the capacity is wanted elsewhere4120. Reserved capacity is paid for whether you use it or not, and for this card it ranges from GPUBank's $0.76 for a week or a month and CloudRift's $0.89 for three months to Hyperstack's $1.361218. Serverless offers bill only the seconds in which a request or job runs, at an hourly equivalent of $1.60 to $2.72, which pays off only when the GPU would otherwise sit idle most of the time13145.
Two traps recur on this card. The first is the minimum unit: Lambda, Crusoe and every large cloud except Google sell the 80 GB SXM only as an eight-GPU instance, so a per-GPU figure of $2.79 is in practice a bill of $22.32 an hour621. The second is the static price page: Vast.ai's A100 SXM4 page showed "No current offers" when we fetched it, while its live offers API listed eight rentable 80 GB machines at the same moment, and Lium showed a reference price of $0.70 with no pod available, so a marketplace figure is only real at the moment you can actually launch on it22423.
Managed on demandA fixed machine at one hourly price.
MarketplaceHosts set their own price; machines vary.
Spot and interruptibleCheaper hours that can be taken back.
ReservedCommitted for a term, paid either way.
ServerlessBilled by active seconds.
04 / Provider by provider
What each price buys, and what it leaves out.
The captures below were taken on 16 Oct 2026 from each provider's own A100 or pricing page, so every figure can be read next to the conditions printed beside it.
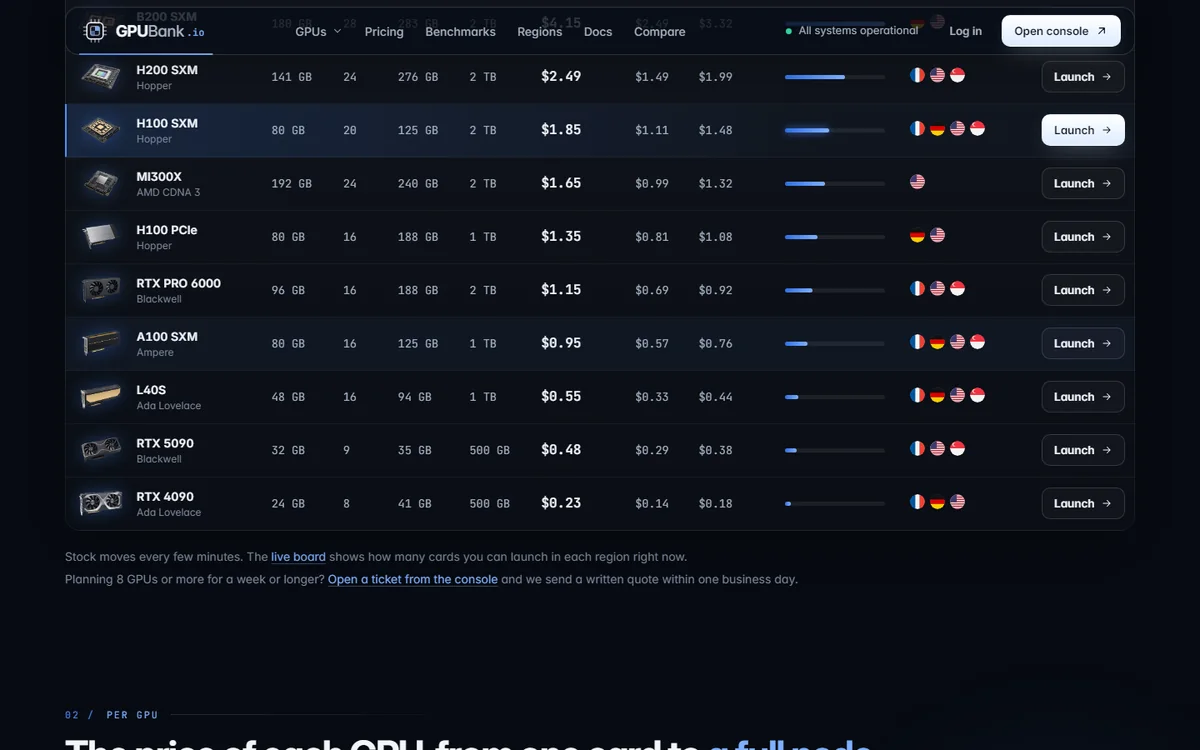
GPUBankAll-in
$0.95/hr
Managed on demand · Paris, Frankfurt, Ashburn, Singapore
16 vCPU125 GB RAM1 TB NVMeIPv4All trafficDisk $0.03/GB-mo
GPUBank lists the A100 SXM at $0.95 an hour on demand, $0.000264 a second, in machines of one to eight cards joined by NVLink, and the rate covers 16 vCPU, 125 GB of RAM and a 1 TB local NVMe disk per GPU, one public IPv4 address and every byte sent or received. The only other line a bill can carry is a persistent disk at $0.03 per GB-month. Billing is per second with no minimum and starts only once the machine has passed its health check, a failed launch is not billed, and a host failure during a job restarts the machine on a healthy host with the same disk and credits the session in full. The interruptible tier costs $0.57 with five minutes of notice and a stop rather than a deletion, and a week or a month reserved costs $0.76. Payment is a prepaid balance topped up in crypto from 25 dollars, with a bonus that brings the effective hour to between $0.79 and $0.59; cards are not accepted for now1.1
Checked 16 Oct 2026
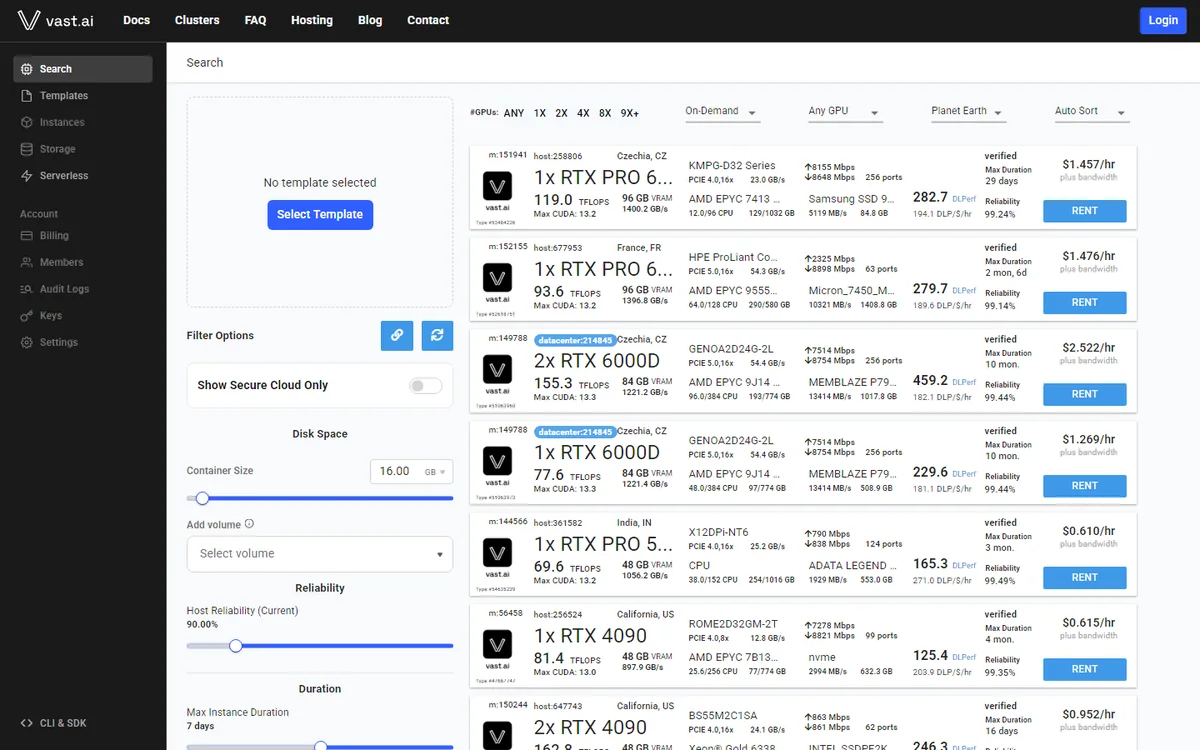
 Vast.ai
$0.94/hr
Marketplace · host-set prices, 1 to 8 GPUs
Host's CPU and RAM shareStorage at host rateBandwidth per GBInterruptible from about $0.53
Vast.ai's live offers API listed eight rentable A100 SXM4 80 GB machines on 16 October 2026, the cheapest at $0.937 per GPU-hour on demand on a host in Iowa with 32 CPU cores and a reliability score of 0.97, the same host in one, two, four and eight-GPU sizes, and a French host at about $1.004. Interruptible minimum bids on those machines started at about $0.53. The headline is not the whole bill: that host charged about $0.33 per GB-month for storage and $0.004 per GB of bandwidth, and Vast bills storage for as long as an instance exists, running or stopped29. The cheaper A100 SXM4 rows in the same search, from $0.47, were 40 GB cards, and the public price page showed "No current offers" because it does not render live listings22. Read a listing's reliability, its storage rate and its uplink before comparing it with a managed price.4
Checked 16 Oct 2026
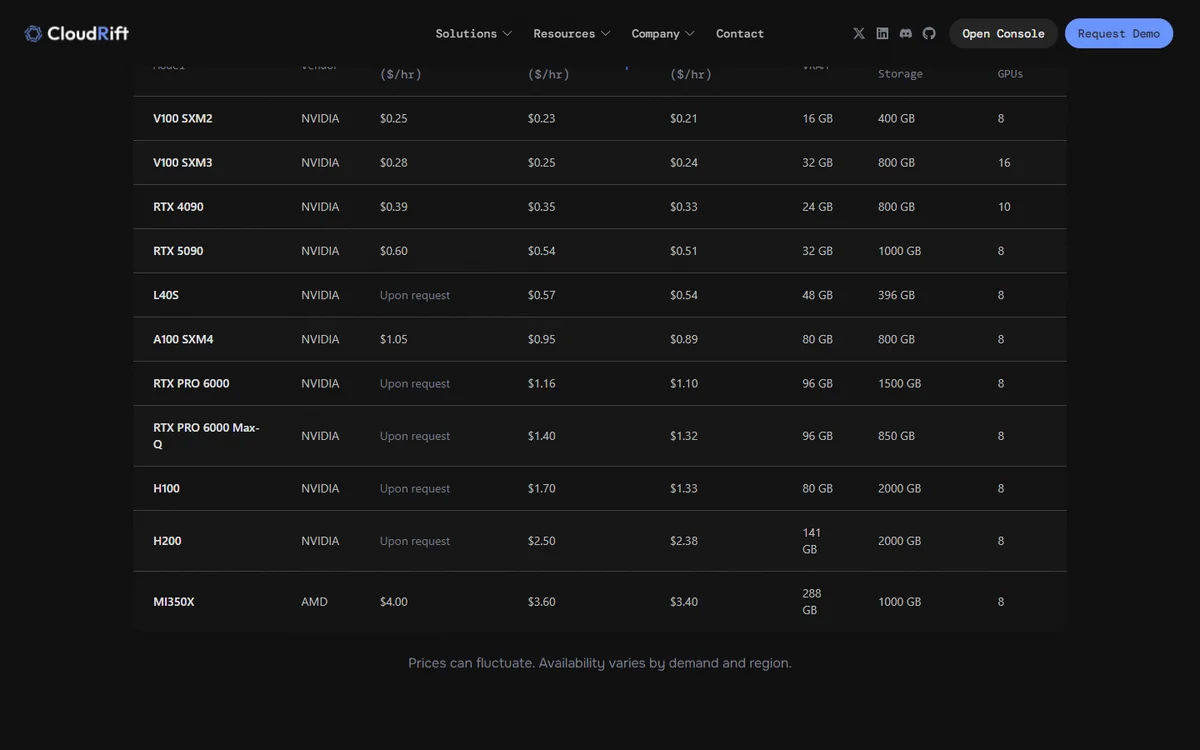
 CloudRift
$1.05/hr
Managed on demand · up to 8 GPUs per instance
800 GB local storageNetworking$0.95 one month$0.89 three months
CloudRift is the closest managed competitor on price. Its pricing page lists the A100 SXM4 80 GB at $1.05 an hour on demand, $0.95 on a one-month commitment and $0.89 on three months, with 800 GB of local storage per GPU, instances of up to eight cards and billing by the second2. The page does not state the vCPU and RAM that come with each card, the regions or live stock, nor a price for storage that survives an instance, so a workflow that keeps datasets between runs has to plan for re-uploading them or for an extra line we could not price. For a buyer who wants a managed single-GPU machine paid by card, it is the cheapest option we found, ten cents above GPUBank's list price, and its three-month rate is the cheapest reservation outside GPUBank's own.2
Checked 16 Oct 2026
 Thunder Compute
$1.09/hr
Managed on demand · variant not stated
8 vCPU64 GB RAM100 GB diskExtra vCPU $0.04/hrReserved $1.49 from 8 GPUs
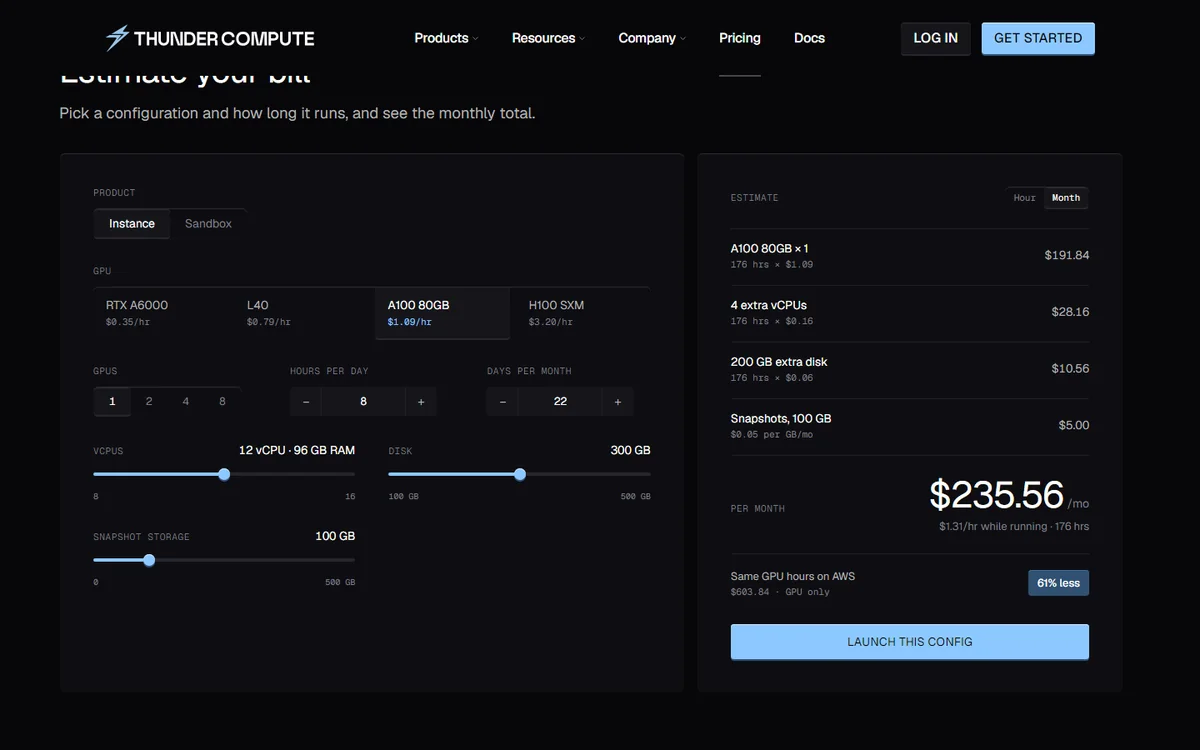
Thunder Compute lists an "A100 80GB" at $1.09 an hour, billed per minute, with 8 vCPU, 64 GB of RAM and the first 100 GB of disk per GPU included, and lets you add vCPUs at $0.04 an hour each up to 16 and disk up to 500 GB3. Its page labels its H100 as SXM but does not say whether the A100 is the SXM module or the PCIe card, so this row is not strictly comparable with the SXM offers around it. Reserved capacity is quoted at $1.49 per GPU-hour from 8 up to more than 512 GPUs, which is above its own on-demand rate and is aimed at teams that need guaranteed capacity rather than a lower price. The machine is smaller than GPUBank's or Beam's, so a data-loading-heavy fine-tune may need the paid vCPU upgrade, which narrows the price gap with the managed offers above it.3
Checked 16 Oct 2026
 Massed Compute
$1.38/hr
Managed on demand · United States
14 vCPU100 GB RAM625 GB storage8 GPUs at $11.04/hr
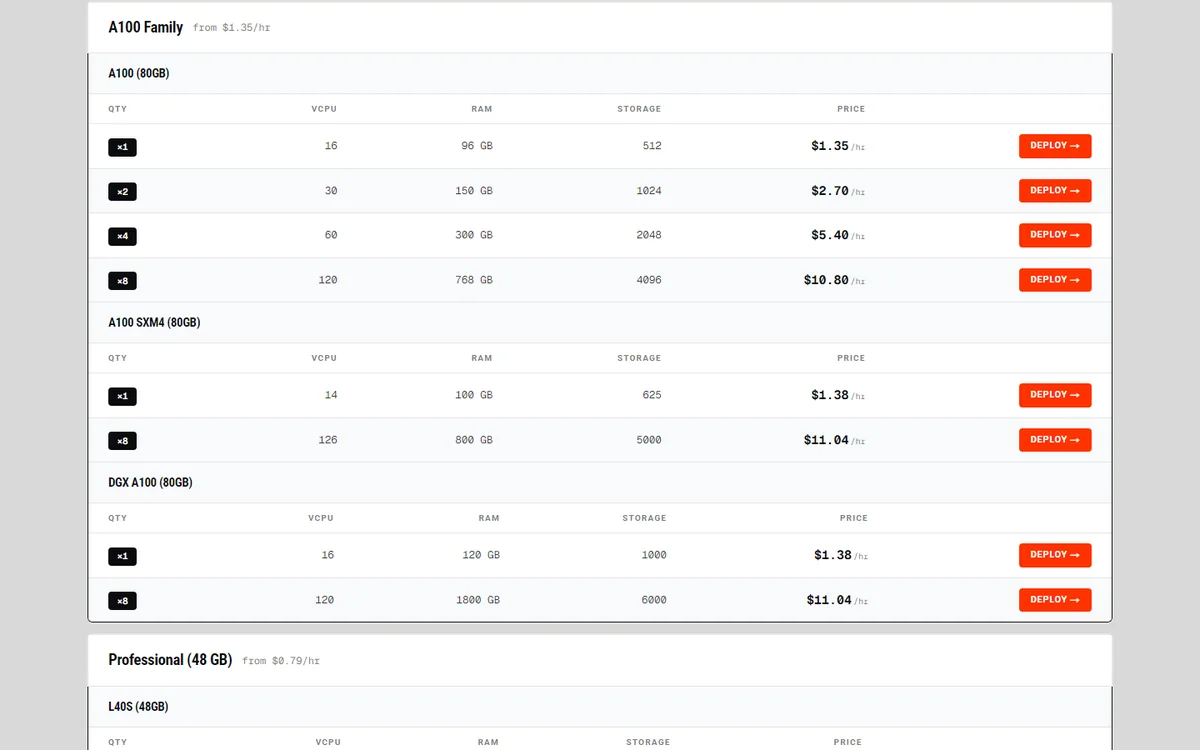
Massed Compute lists the A100 SXM4 80 GB at $1.38 an hour for a single card with 14 vCPU, 100 GB of RAM and 625 GB of storage, and at $11.04 an hour for an eight-GPU machine, which is the same $1.38 per GPU17. It also lists a plain "A100 (80GB)" from $1.35 and a DGX A100 at $1.38 per GPU, so check which line you launch. The page does not show live stock, and Massed Compute capacity is also resold by brokers and other clouds, which is why the same machine shape appears under several names in aggregator tables. Among single-GPU managed offers it sits in the middle of the market, about 45 percent above GPUBank and 23 percent below Runpod Secure Cloud, with one of the few published eight-GPU A100 SXM prices that does not rise per GPU when you scale up.17
Checked 16 Oct 2026
 Runpod
$1.79/hr
Secure Cloud on demand · per second
16 vCPU125 GB RAMNo traffic chargesVolume $0.10 to $0.20/GB-moServerless $2.72/hr
Runpod's pricing page, updated on 8 October 2026, lists the A100 SXM 80 GB at $1.79 an hour on Secure Cloud with 16 vCPU and 125 GB of RAM, billed per second with no traffic charges, up from $1.59 at the end of September5. Disks are extra: container and volume disks cost $0.10 per GB-month while the pod runs, an idle volume $0.20, and network storage $0.07 per GB-month under 1 TB and $0.05 above. The structured data in the page still gives $1.39 for an A100 SXM on Community Cloud, its peer-hosted tier, but the visible table did not show that row, and Runpod Serverless charges $2.72 an hour for an A100 80 GB worker. Runpod costs nearly twice GPUBank's rate for a similar machine; what it offers in return is card payment, a very large template ecosystem and the serverless product on the same account.5
Checked 16 Oct 2026
Where GPUBank wins, and where it does not
GPUBank rents the A100 SXM at $0.95 per GPU-hour on demand, $0.000264 a second or $693.50 for a 730-hour month, with 16 vCPU, 125 GB of RAM and a 1 TB local NVMe disk per GPU, in machines of one to eight cards joined by NVLink at 600 GB/s1. The price includes the vCPU, the RAM, the local NVMe, one public IPv4 address and all inbound and outbound traffic, and the only other line a bill can carry is a persistent disk at $0.03 per GB-month. Billing is per second with no minimum and starts only once the machine has passed its health check, a failed launch is not billed, a stopped machine costs only its persistent disk, and a host that fails during a job restarts the machine on a healthy host with the same disk and credits the interrupted session in full. The interruptible tier costs $0.57 with five minutes of notice, and a week or a month reserved costs $0.76, prepaid and cancellable before it starts1.
That makes GPUBank the cheapest A100 SXM we found that comes as a whole machine, a cent above the cheapest marketplace listing, and its effective hour falls to $0.79 with a 25 dollar top-up and $0.59 with a 1,000 dollar top-up thanks to a balance bonus on credit that never expires1. It loses in three places. A Vast.ai interruptible bid of about $0.53 undercuts its $0.57 spot tier for a buyer who accepts being outbid without notice4. For throughput-bound jobs its own H100 SXM at $1.85 is often cheaper per finished job, as the measurements further down show. And GPUBank takes only prepaid top-ups in crypto, from 25 to 5,000 dollars, with cards not accepted for now, so a team that must pay by card should look at CloudRift, Thunder Compute or Runpod instead1.
The rest of the market
Beyond the six offers shown as cards, several managed clouds sell a single A100 80 GB at prices between $1.36 and $2.00. Beam lists an A100 80 GB SXM4 machine from $1.36 an hour with 16 vCPU, 128 GB of RAM and 1 TB of NVMe, one of the most generous machines in this price range16. Jarvislabs charges $1.49 with 16 vCPU and 112 GB of RAM, billed per minute, without saying SXM or PCIe on its pricing page, and GetDeploying showed Geodd's A100 SXM with 16 vCPU and 120 GB and Sesterce's unlabelled A100 80 GB, both at $1.49 and in stock on 15 October9; and Hyperstack lists its A100 SXM at $1.60 on demand and $1.36 reserved, with up to 24 pCPU and 120 GB of RAM, next to a PCIe A100 at $1.351218. Verda, formerly DataCrunch, now shows $1.996 per GPU-hour for its A100 SXM4 80 GB in one, two, four and eight-GPU sizes, up from the $1.79 we recorded at the end of September, with 22 CPUs and 120 GB of RAM listed against the card19. Above that range, and only by the eight-GPU instance, Crusoe lists an A100 80 GB SXM at $2.30 per GPU-hour next to a PCIe version at $2.00, and Lambda sells its A100 SXM 80 GB as an eight-GPU instance at $2.79 per GPU with 240 vCPU, 1,800 GiB of RAM and 19.5 TiB of SSD216.
Marketplace floors also say little about a reliable host: Thunder Compute's review of 9 October priced three Vast.ai A100 80 GB hosts at a median of $1.63 per GPU-hour, between $1.21 and $1.76, with 100 GB of storage counted and bandwidth on top, against the $0.94 floor we found a week later; the same review puts Paperspace's A100 80 GB at $3.18 and CoreWeave's eight-GPU node at $2.70 per GPU24. On the marketplace and serverless side, TensorDock advertises A100 80 GB hosts from $1.42 to $1.63 an hour depending on which line of its page you read, and spot from $0.67, on a mix of SXM hosts in Prague and Oregon and PCIe hosts in Devon, so the variant depends on the listing25. Lium had no A100 SXM pod available when we checked and showed only a reference price of $0.70, and Runpod's Community Cloud figure of $1.39 appears in its page's structured data but not in the visible table235. For per-second work, Koyeb lists an A100 80 GB at $1.60 an hour and an A100 SXM at $2.15, both with 15 vCPU and 180 GB of RAM, Modal charges $0.000694 a second, or $2.50 an hour, with CPU and memory billed on top, and Runpod Serverless charges $2.72 an hour for an A100 80 GB worker13145. On Runpod's own prices a serverless worker beats a Secure Cloud pod left running only while it is busy less than about 66 percent of the time, $1.79 divided by $2.72.
The large clouds
The large clouds sell the A100 80 GB almost only by the eight-GPU instance, and their per-GPU price is the instance price divided by eight. AWS's p4de.24xlarge, with eight 80 GB cards, 96 vCPU and 1,152 GiB of RAM, costs $27.447 an hour on demand in Vantage's default view, or $3.43 per GPU, after the price cut AWS announced for its GPU instances in June 2025; in 2022 AWS's own page listed the same instance at $40.9672627. The older p4d.24xlarge, at $21.958, carries 40 GB cards and does not belong next to an 80 GB price11. Vantage shows the p4de spot price at $20.736 an hour and a three-year reservation at $11.718, or $1.46 per GPU. Microsoft's own Retail Prices API lists the ND96amsr A100 v4, eight 80 GB SXM4 cards, at $32.77 an hour for Linux pay-as-you-go in East US, $4.10 per GPU and unchanged since December 2021, with spot at $8.44 an hour, about $1.06 per GPU, and a three-year reservation that works out to about $1.80 per GPU20.
Google Cloud is the one large cloud that rents a single A100 80 GB, as a2-ultragpu-1g with 12 vCPU and 170 GB of RAM, at $5.07 an hour on demand and $3.04 on spot in us-central1, figures we took from gcloud-compute.com's update of 11 October because Google's own price tables did not render for us8. Oracle's eight-GPU bare-metal A100 shape costs $32.00 an hour, $4.00 per GPU, read from Economize's update of 8 October because Oracle's price list refused our requests28. These clouds also bill outbound traffic, block storage and, on most of them, public addresses on top. You pay their prices for quota-backed capacity, compliance coverage and integration with the rest of their services rather than for the GPU, which is why a team already committed to one of them may still rationally pay three to five times the specialised-cloud rate.
05 / Every offer
The whole comparison, sorted by kind and price.
| Provider | USD / GPU-hr | Kind | Unit | What the price includes | Billing | Stock | Basis |
|---|---|---|---|---|---|---|---|
| GPUBank | $0.95 | Managed on demand | 1 GPU | 16 vCPU, 125 GB RAM, 1 TB NVMe, IPv4, traffic | Per second | In stock | Provider page1 |
| CloudRift | $1.05 | Managed on demand | 1 GPU | 800 GB local storage per GPU | Per second | Not stated | Provider page2 |
| Thunder Compute | $1.09 | Managed on demand | 1 GPU | 8 vCPU, 64 GB RAM, 100 GB disk; variant not stated | Per minute | Not stated | Provider page3 |
 Beam | $1.36 | Managed on demand | 1 GPU | 16 vCPU, 128 GB RAM, 1 TB NVMe | Not stated | Not stated | Provider page16 |
| Massed Compute | $1.38 | Managed on demand | 1 GPU | 14 vCPU, 100 GB RAM, 625 GB storage | Not stated | Not stated | Provider page17 |
 Jarvislabs | $1.49 | Managed on demand | 1 GPU | 16 vCPU, 112 GB RAM; variant not stated | Per minute | Not stated | Provider page12 |
 Hyperstack | $1.60 | Managed on demand | 1 GPU | CPU, RAM and ephemeral NVMe included | Not stated | Not stated | Provider page18 |
| Runpod | $1.79 | Managed on demand | 1 GPU | 16 vCPU, 125 GB RAM; disks extra | Per second | Not stated | Provider page5 |
 Verda | $2.00 | Managed on demand | 1 GPU | 22 CPUs, 120 GB RAM | Not stated | Not stated | Provider page19 |
 Crusoe | $2.30 | Managed on demand | 1 GPU | Machine not detailed on the price list | Not stated | Not stated | Provider page21 |
 Lambda | $2.79 | Managed on demand | 8-GPU node | 240 vCPU, 1,800 GiB RAM, 19.5 TiB SSD | Not stated | Not stated | Provider page6 |
 Lium | $0.70 | Marketplace | 1 GPU | Reference price only | Not stated | Sold out | Provider page23 |
| Vast.ai | $0.937 | Marketplace | 1 GPU | 32 CPU cores; storage $0.33/GB-mo, bandwidth extra | Per second | In stock | Provider page4 |
| Runpod Community | $1.39 | Marketplace | 1 GPU | Structured data only, not in the visible table | Per second | Not stated | Provider page5 |
 TensorDock | $1.42 | Marketplace | 1 GPU | Host-dependent; SXM and PCIe hosts mixed | Not stated | Not stated | Provider page25 |
| Vast.ai | $0.534 | Spot and interruptible | 1 GPU | Minimum bid; can be outbid | Per second | In stock | Provider page4 |
| GPUBank | $0.57 | Spot and interruptible | 1 GPU | As on demand, 5 min notice, disk kept | Per second | In stock | Provider page1 |
| TensorDock | $0.67 | Spot and interruptible | 1 GPU | Host-dependent; variant mixed | Not stated | Not stated | Provider page25 |
 Microsoft Azure | $1.06 | Spot and interruptible | 8-GPU node | ND96amsr A100 v4, East US, Linux | Per second | Not stated | Provider page20 |
 AWS | $2.59 | Spot and interruptible | 8-GPU node | p4de.24xlarge, Vantage default view | Per second | Not stated | Aggregator7 |
 Google Cloud | $3.04 | Spot and interruptible | 1 GPU | a2-ultragpu-1g, 12 vCPU, 170 GB RAM, us-central1 | Per second | Not stated | Aggregator8 |
| GPUBank | $0.76 | Reserved | 1 GPU | Week or month, prepaid | Per term | In stock | Provider page1 |
| CloudRift | $0.89 | Reserved | 1 GPU | Three months | Per term | Not stated | Provider page2 |
| CloudRift | $0.95 | Reserved | 1 GPU | One month | Per term | Not stated | Provider page2 |
| Hyperstack | $1.36 | Reserved | 1 GPU | Reservation | Per term | Not stated | Provider page18 |
| AWS | $1.46 | Reserved | 8-GPU node | p4de.24xlarge, three years | Per term | Not stated | Aggregator7 |
| Thunder Compute | $1.49 | Reserved | cluster | 8 to 512+ GPUs | Per term | On request | Provider page3 |
| Microsoft Azure | $1.80 | Reserved | 8-GPU node | ND96amsr A100 v4, three years, East US | Per term | Not stated | Provider page20 |
| AWS | $3.43 | Large clouds | 8-GPU node | p4de.24xlarge, 96 vCPU, 1,152 GiB RAM | Per second | Not stated | Aggregator7 |
 Oracle Cloud | $4.00 | Large clouds | 8-GPU node | BM.GPU.A100-v2.8 bare metal | Not stated | Not stated | Aggregator28 |
| Microsoft Azure | $4.10 | Large clouds | 8-GPU node | ND96amsr A100 v4, East US, Linux | Per second | Not stated | Provider page20 |
| Google Cloud | $5.07 | Large clouds | 1 GPU | a2-ultragpu-1g, 12 vCPU, 170 GB RAM, us-central1 | Per second | Not stated | Aggregator8 |
 Koyeb | $1.60 | Serverless | 1 GPU | A100 80 GB, 15 vCPU, 180 GB RAM; variant not stated | Per second | Not stated | Provider page13 |
| Koyeb | $2.15 | Serverless | 1 GPU | A100 SXM, 15 vCPU, 180 GB RAM | Per second | Not stated | Provider page13 |
 Modal | $2.50 | Serverless | 1 GPU | GPU only, CPU and RAM extra; variant not stated | Per second | Not stated | Provider page14 |
| Runpod Serverless | $2.72 | Serverless | 1 GPU | A100 80 GB worker | Per second | Not stated | Provider page5 |
"Aggregator" rows could not be read on the provider's own page that day; "Provider snapshot" rows come from a page dated by the provider.
06 / The real monthly bill
What an A100 hour really costs
Storage is the line that bills while nothing runs. A 200 GB persistent disk costs $6.00 a month on GPUBank at $0.03 per GB-month and $14.00 on Runpod's network storage at $0.07, while a Runpod volume disk costs $0.10 per GB-month while the pod runs and $0.20 while it sits idle15. Thunder Compute includes 100 GB of disk and charges $0.219 per GB-month beyond it, so its 200 GB would add about $21.903. On Vast.ai each host sets its own storage rate and Vast bills storage for as long as the instance exists, running or stopped; the cheapest 80 GB host on the day charged about $0.33 per GB-month, so the same 200 GB kept all month would cost about $66.60, eleven times the GPUBank disk, and its bandwidth was priced at $0.004 per GB429. A stopped marketplace instance also keeps its data but not its claim on the GPU, so if another renter takes the card you either wait or move your data to another host.
Billing granularity matters most for short jobs. A job of 61 minutes on a per-second meter at $0.95 costs $0.97, while a provider that bills each started hour charges two hours, $1.90 at the same rate; Thunder Compute and Jarvislabs bill per minute, CloudRift, Runpod and GPUBank per second312251. On an eight-GPU-only cloud the unit itself is the cost: a quick test on Lambda's A100 80 GB instance bills $22.32 an hour for all eight cards even if the code uses one6. Prepaid models add their own terms: GPUBank's balance never expires and its top-up bonus lowers the effective hour, but the money is committed up front, so the bonus is worth having only for credit you will actually spend1.
The last cost is lost time, and the question is who pays for it. On GPUBank a launch that fails its health check is not billed and a host failure during a job is credited for the whole interrupted session1. On a marketplace a host that disappears ends your session and the work since the last checkpoint is yours to lose, which is why Vast.ai publishes a reliability score for every listing and why the best-scored hosts are rarely the cheapest4. A reclaimed spot instance costs whatever was done since the last checkpoint: with GPUBank's five-minute notice and checkpoint hook that can be close to nothing, while an outbid marketplace instance with no checkpointing can cost the whole run.
Three workloads, priced for a month
GPUBank interruptible
40 h GPU$22.80
Storage$6.00
OtherNone
Month$28.80
Runs checkpoint; no reclaim losses counted
All-inCloudRift
40 h GPU$42.00
Storage$0.00
OtherPersistent storage not priced
Month$42.00
Data re-uploaded to the 800 GB local disk each run
GPUBank
40 h GPU$38.00
Storage$6.00
OtherNone
Month$44.00
On demand, list price
All-inRunpod Secure Cloud
40 h GPU$71.60
Storage$14.00
OtherNone
Month$85.60
Network storage at $0.07/GB-mo
Vast.ai
40 h GPU$37.48
Storage$66.60
OtherBandwidth $0.004/GB
Month$104.08
Iowa host, instance kept all month to hold the disk
GPUBank's interruptible tier wins at $28.80, 40 hours at $0.57 plus $6.00 of disk, as long as each run writes checkpoints. CloudRift's $42.00 looks slightly cheaper than GPUBank's on-demand $44.00, $38.00 of GPU time plus $6.00 of disk, but only because it publishes no price for storage that survives an instance, so the $42.00 holds only if you re-upload 200 GB before every run. Runpod costs $71.60 plus $14.00 of network storage, $85.60. The Vast.ai host that is cheapest per hour becomes the most expensive here: $37.48 of GPU time is followed by about $66.60 of storage, because Vast bills the disk for as long as the instance exists and this host charges $0.333 per GB-month. With a 100 dollar top-up, GPUBank's on-demand bill falls to about $32.59 of cash.
GPUBank interruptible
730 h GPU$416.10
Storage$3.00
OtherRestarts after reclaim
Month$419.10
No reclaim losses counted
All-inVast.ai interruptible
730 h GPU$389.82
Storage$33.30
OtherBandwidth $0.004/GB
Month$423.12
Minimum bid holds all month; can be outbid
GPUBank reserved
730 h GPU$554.80
Storage$3.00
OtherNone
Month$557.80
One month, prepaid
All-inCloudRift three months
730 h GPU$649.70
Storage$0.00
OtherNone
Month$649.70
Three-month commitment, local storage included
GPUBank
730 h GPU$693.50
Storage$3.00
OtherNone
Month$696.50
On demand, list price
All-inVast.ai
730 h GPU$684.01
Storage$33.30
OtherBandwidth $0.004/GB
Month$717.31
Iowa host stays up all month
For a queue that can absorb interruptions, GPUBank's interruptible tier at $416.10 plus $3.00 of disk, $419.10, and a Vast.ai bid at $0.534, $389.82 plus $33.30 of storage or $423.12, cost about the same, with the difference that GPUBank gives notice and keeps the disk while an outbid Vast instance simply stops. For a service that must stay up, a GPUBank month reserved at $0.76 comes to $557.80, below CloudRift's three-month rate of $649.70 and well below either provider's on-demand month, $696.50 on GPUBank and $717.31 on the Vast host once its storage is counted. With 1,000 dollar top-ups GPUBank's on-demand month costs about $433 of cash. If the volume is fixed rather than the hours, the H100 changes the answer: on short-sequence serving it does the same work for about 26 percent less.
GPUBank interruptible
100 h GPU$456.00
Storage$30.00
OtherNone
Month$486.00
Checkpointing every few minutes
All-inGPUBank
100 h GPU$760.00
Storage$30.00
OtherNone
Month$790.00
8-GPU NVLink machine on demand
All-inCloudRift
100 h GPU$840.00
Storage$0.00
OtherPersistent storage not priced
Month$840.00
Up to 8 GPUs per instance
Microsoft Azure spot
100 h GPU$844.16
Storage$0.00
OtherDisks and egress extra
Month$844.16
ND96amsr A100 v4, East US, eviction risk
Vast.ai
100 h GPU$747.20
Storage$333.00
OtherBandwidth $0.004/GB
Month$1,080.20
Iowa 8-GPU host at $0.934 per GPU-hour, instance kept all month
Lambda
100 h GPU$2,232.00
Storage$0.00
OtherNone
Month$2,232.00
8-GPU instance, 19.5 TiB SSD included
Eight cards for 100 hours cost $456.00 plus $30.00 of disk on GPUBank's interruptible tier, $486.00, and $760.00 plus $30.00 on demand, $790.00, which is the cheapest uninterruptible price here. CloudRift's $840.00 and Azure's spot instance at $844.16 come next, but neither figure includes storage, and Azure's can be evicted. Vast.ai's eight-GPU host costs $747.20 of GPU time, less than GPUBank, and then about $333.00 for keeping 1 TB on it all month, $1,080.20; deleting the instance between runs saves that but loses the data. Lambda's eight-GPU instance costs $2,232.00 with generous local SSD. A one-week GPUBank reservation, 1,344 card-hours at $0.76 or $1,021.44, only pays off from about 135 hours of use in that week.
07 / Measured per job
Performance, measured, and the right tool
The A100 SXM is the sensible rental when a job needs 80 GB of fast memory but not FP8, when it is memory-bound or spends much of its time idle rather than saturating the tensor cores, or when the software stack predates Hopper: QLoRA and LoRA fine-tuning of 7B to 70B models, BF16 batch inference, notebooks left open for hours and MIG slices for small services. It is the wrong tool for FP8 serving at high concurrency, for pretraining at scale and for any long throughput-bound job where the H100's speed repays its higher rate. The measured gap depends heavily on the workload. In MLPerf Training v2.1, eight A100 SXM 80 GB took 16.88 minutes to train BERT-large against 6.38 minutes for eight H100 SXM, a ratio of 2.65, while ResNet-50 took 28.69 against 14.68 minutes, a ratio of only 1.953031. The H100's BERT entry used FP8 through the Transformer Engine, which is part of why the gap is wider there32.
Inference shows the same pattern. E2E Networks' TensorRT-LLM offline benchmark of Llama 3.1 8B on one GPU gives 6,051.62 tokens per second on the A100 against 15,861.63 on the H100 with 128 input and 128 output tokens, a ratio of 2.62, but only 3,747.46 against 7,425.07 with 1,000 input and 1,000 output tokens, a ratio of 1.9833. That page does not state the precision, the software version or the A100's form factor, and it shows a third, unlabelled H100 column at 27,006.16 tokens per second that may be an FP8 run, so we use the like-for-like column and treat the figures as indicative. The results therefore agree on direction and disagree on size: the H100 is about twice as fast on bandwidth-limited or long-sequence work and two and a half to nearly three times as fast on short, compute-heavy work, and more again when it runs FP8 and the A100 cannot.
MLCommons v2.1 NVIDIA run logs, scored with the MLPerf rule (best and worst runs dropped); EE Times reported 16.8 and 6.4 minutes. H100 used FP8.30
MLCommons v2.1 NVIDIA run logs, scored with the MLPerf rule; EE Times gave 28.2 minutes for the closest 8x A100 score.30
E2E Networks TIR inference benchmarks, page updated 15 May 2026; precision, version and form factor not stated.33
WHOLE MACHINE
$0.95
GPUBank on demand, CPU, RAM, NVMe, IPv4 and traffic included
MARKET MEDIAN
$1.88
GetDeploying, 39 priced providers, 15 Oct 2026
BERT RUN, 8 GPUS
$2.14
on A100s against $1.57 on H100s at GPUBank rates
08 / H100 or the others
Per job against the other cards
On GPUBank the H100 SXM costs $1.85 an hour against $0.95 for the A100 SXM, 1.95 times as much, so the H100 is cheaper per job whenever it runs more than 1.95 times faster. On the measurements above that threshold is crossed on BERT, where a training run costs $2.14 on eight A100s and $1.57 on eight H100s, and on short-sequence LLM serving, where a million tokens cost $0.044 on the A100 and $0.032 on the H10030331. It is not crossed on ResNet-50, at $3.63 against $3.62, or on long-sequence serving, at $0.070 against $0.069 per million tokens, where the two cards tie. The top-up bonus and the interruptible tier apply the same factor to every card, so neither changes this ranking, and the result holds as long as the job keeps the GPU busy; idle time is billed at the hourly rate on both cards, which favours the cheaper one.
We found no measurement from a named source that ran the H100 PCIe, the L40S or the RTX PRO 6000 against the A100 SXM on the same test, so we do not compute a cost per job for them. From the specifications alone, the L40S at $0.55 has 48 GB of GDDR6 at 864 GB/s, less than half the A100's bandwidth, so it is unlikely to win on memory-bound decoding, but it has FP8 and costs 58 percent of the A100's rate for models that fit in 48 GB. The RTX PRO 6000 at $1.15 has 96 GB at 1.8 TB/s, more memory for 1.21 times the price, and the H100 PCIe at $1.35 has the same 80 GB of HBM2e at 2.0 TB/s with Hopper's FP8 but no NVLink between cards1.
L40S
48 GB GDDR6 ECC · 864 GB/s
$0.55/hr
Stable Diffusion, video, Whisper transcription and embeddings
A100 SXM
80 GB HBM2e · 2.0 TB/s
$0.95/hr
LoRA and QLoRA fine-tuning, batch inference
RTX PRO 6000
96 GB GDDR7 ECC · 1.8 TB/s
$1.15/hr
Serving 70B models in 4-bit and AI video generation
H100 PCIe
80 GB HBM2e · 2.0 TB/s
$1.35/hr
Single-GPU training and inference on a budget
H100 SXM
80 GB HBM3 · 3.35 TB/s
$1.85/hr
AI training, fine-tuning and production LLM inference
GPUBank on-demand prices, all-in. Memory bar scaled to 96 GB.
09 / Rent or buy
Rent or buy an A100 SXM
The realistic purchase unit is a whole eight-GPU HGX system, because the SXM4 module has no PCIe connector and needs a baseboard with its power delivery and cooling. AmCompute values a used HGX A100 node with eight 80 GB cards at $95,200 in October 2026 and reports realised sales of single SXM4 80 GB modules at about $4,700 to $5,400 over the twelve months to August 2026, down about 35 percent on the year before. Asking prices are higher: Caladan Semi recorded a median ask of $9,925 from only four US listings on 9 September, and Jarvislabs gives $5,000 to $9,000 for a used module and $80,000 to $120,000 for a used DGX A10034353637. We use $95,200 for the server and assume that it keeps losing about 35 percent of its value a year, which leaves roughly $40,000 of resale value after two years.
Depreciation is then $95,200 minus $40,000 divided by 24 months, $2,300 a month for the whole server or $287.50 per GPU. Power at an assumed 5 kW under load, below the 6.5 kW maximum NVIDIA gives for a DGX A100, at the US average of 18.19 cents per kWh adds $0.91 per machine-hour, about $0.11 per GPU-hour3839. Against GPUBank's $0.95 on-demand rate the break-even is $287.50 divided by $0.84, about 344 hours per GPU per month or 47 percent utilisation; against the $0.76 reserved rate it is 445 hours, and against the $0.59 effective rate with 1,000 dollar top-ups it is 599 hours, 82 percent. Rack space, cooling, networking, spare modules and the engineer who keeps the box running are not counted, and all of them push the break-even higher, so buying makes sense only for a team that already runs a data-centre rack and can keep eight cards busy most of every day for two years.
| Hours a month | Rent at $0.95 | Rent at $0.59 effective | Own | Cheaper |
|---|---|---|---|---|
| 100 | $760.00 | $475.00 | $2,390.95 | Rent |
| 250 | $1,900.00 | $1,187.50 | $2,527.38 | Rent |
| 344 | $2,614.40 | $1,634.00 | $2,612.87 | Even at list price; rent with the bonus |
| 445 | $3,382.00 | $2,113.75 | $2,704.73 | Own beats list and reserved; rent with the bonus |
| 600 | $4,560.00 | $2,850.00 | $2,845.70 | Even with the bonus; own at list |
| 730 | $5,548.00 | $3,467.50 | $2,963.93 | Own |
AmCompute valuation of a used HGX A100 8x 80 GB node, October 2026
10 / What to choose
The cheapest A100 depends on the job.
Fine-tuning a 7B to 70B model with LoRA or QLoRA
A100 SXM, interruptible if your runs checkpoint
80 GB fits a 70B model at 4-bit with room for context, and these runs spend enough time on data and checkpoints that the H100's speed is not fully used.
Serving an LLM at high concurrency or in FP8
H100 SXM
It was 2.6 times faster on short-sequence serving in E2E's test, so at 1.95 times the price it costs about a quarter less per million tokens.
Notebooks, debugging and legacy CUDA stacks
A100 SXM on demand
Idle time is billed at the hourly rate, so the cheaper card wins, and Ampere-era code runs without porting work.
Multi-GPU training for a few days
8x A100 SXM, or 8x H100 for transformer training
On MLPerf the A100 tied the H100 per job on ResNet-50 and lost on BERT; per-second billing on an NVLink machine avoids paying for an idle week.
11 / Questions
What people ask before renting one.
The cheapest A100 SXM 80 GB hour on 16 October 2026 was an interruptible bid of about $0.53 on a Vast.ai host in Iowa, and the cheapest on-demand listing was the same host at $0.937 per GPU-hour4. Those are marketplace prices: storage, at $0.333 per GB-month on that host, and bandwidth are billed separately, and the machine and its reliability depend on the host. The cheapest price for a whole managed machine was GPUBank's $0.95, with 16 vCPU, 125 GB of RAM, a 1 TB NVMe disk, an IPv4 address and traffic included, followed by CloudRift at $1.05 and Thunder Compute at $1.09123. GPUBank's interruptible tier costs $0.57 and its top-up bonus brings the effective on-demand hour down to $0.59. Many cheaper-looking rows on aggregators are 40 GB or PCIe cards, so check the variant first.
An A100 SXM 80 GB cost between about $0.94 and $5.07 per GPU-hour on demand in October 2026, depending on the kind of offer. Marketplace hosts start around $0.94, managed single-GPU clouds charge $0.95 to $2.00 (GPUBank $0.95, CloudRift $1.05, Thunder Compute $1.09, Beam $1.36, Massed Compute $1.38, Jarvislabs $1.49, Hyperstack $1.60, Runpod $1.79, Verda $1.996), and eight-GPU instances cost more per card, with Lambda at $2.794125196. The large clouds are highest: AWS $3.43, Oracle $4.00, Azure $4.10 and Google Cloud $5.07 for its single-GPU shape728208. GetDeploying's median across all A100 variants and 39 providers was $1.88 on 15 October9.
The SXM4 module mounts on an HGX baseboard, runs at up to 400 W, has 2,039 GB/s of memory bandwidth in its 80 GB version and talks to the other cards on the board through NVLink at 600 GB/s, which matters most for multi-GPU training10. The 80 GB PCIe card fits an ordinary server slot, has a lower power limit, slightly less bandwidth and usually no full NVLink mesh, and for a single-GPU job that fits in memory it performs close to the SXM. The 40 GB versions have half the memory and less bandwidth and are a third product. Many listings say only "A100 80GB": Thunder Compute, Jarvislabs, Koyeb and Modal do not state the form factor on their pricing pages, and Lambda's single-GPU A100 is a 40 GB card31213146. Compare SXM with SXM.
Yes, for jobs that need 80 GB of fast memory but gain little from FP8 or raw compute. QLoRA and LoRA fine-tuning, BF16 batch inference on older stacks, long-sequence serving, notebooks left open for hours and MIG partitioning are the strongest cases, and at $0.95 for a whole machine the A100 is the cheapest 80 GB card we found per hour1. It is weaker for compute-heavy work: in MLPerf Training v2.1 eight H100s trained BERT 2.65 times faster than eight A100s, and in E2E Networks' Llama 3.1 8B test the H100 was 2.62 times faster on short sequences, which makes it cheaper per job at GPUBank's $1.853033. On ResNet-50 and long sequences the ratio was close to 2 and the two cards tied per job. Run your own job on both for half an hour before committing.
On GPUBank the H100 SXM is cheaper per job whenever it runs more than 1.95 times faster than the A100 SXM, because that is the ratio of their hourly prices, $1.85 against $0.951. On measured results that is true for BERT training, $1.57 per run on eight H100s against $2.14 on eight A100s, and for short-sequence LLM serving, $0.032 against $0.044 per million tokens3033. It is not true for ResNet-50 training, $3.62 against $3.63, or for long-sequence serving, $0.069 against $0.070 per million tokens, where the cards tie. The H100 gains most where it can use FP8 and at high concurrency; the A100 holds its own on memory-bound work and wins whenever the GPU sits idle part of the time, because idle hours are billed at the hourly rate on both cards.
The cheapest interruptible A100 SXM 80 GB we found on 16 October 2026 was a Vast.ai minimum bid of about $0.53 per GPU-hour on an Iowa host, where a higher bid can take the machine at any time4. GPUBank's interruptible tier costs $0.57 with five minutes of notice through the metadata endpoint, a webhook and the console, a checkpoint hook, and a stop rather than a deletion, and a missed notice credits the last 30 minutes1. TensorDock advertises spot from $0.67 on a mix of SXM and PCIe hosts25. On the large clouds, Azure's eight-GPU ND96amsr A100 v4 spot price is $8.44 an hour in East US, about $1.06 per GPU, AWS's p4de spot is about $2.59 per GPU on Vantage, and Google's single-GPU a2-ultragpu-1g spot is $3.042078.
AWS sells the A100 80 GB only as the p4de.24xlarge instance, with eight GPUs, 96 vCPU and 1,152 GiB of RAM, at $27.447 an hour on demand in Vantage's default view, which is $3.43 per GPU711. AWS's own page lists the instance's specifications but not its current price, and the figure reflects the price reduction AWS announced for its GPU instances in June 2025; in 2022 the same page showed $40.96 an hour2627. The older p4d.24xlarge costs $21.958 an hour but carries A100 40 GB cards and should not be compared with 80 GB offers. Vantage shows p4de spot at $20.736 an hour and a three-year reservation at $11.718, about $1.46 per GPU. You cannot rent a single A100 on AWS, and data transfer out and block storage are billed on top.
You can rent a single A100 SXM 80 GB from many specialised clouds, but several well-known providers sell only eight at a time. GPUBank (machines of one to eight cards), CloudRift, Massed Compute, Beam, Hyperstack, Verda, Runpod and the Vast.ai marketplace all rent one card121716181954. Lambda sells its A100 SXM 80 GB only as an eight-GPU instance at $2.79 per GPU, $22.32 an hour, and its single-GPU A100 is the 40 GB version6. AWS, Azure's ND series and Oracle also sell eight-GPU instances only, while Google Cloud's a2-ultragpu-1g rents a single A100 80 GB at $5.07 an hour8. When a per-GPU price looks low, check the minimum unit and multiply by it before comparing.
One A100 SXM running a full 730-hour month costs $693.50 on GPUBank on demand, $554.80 on a GPUBank monthly reservation and $416.10 on its interruptible tier, before any persistent disk at $0.03 per GB-month1. With the 60 percent bonus on 1,000 dollar top-ups, the on-demand month costs about $433 of cash. CloudRift costs $766.50 on demand and $649.70 on its three-month rate, Thunder Compute $795.70 and Runpod Secure Cloud $1,306.70235. The cheapest Vast.ai host would cost $684.01 of GPU time plus storage at its own rate, about $33.30 for 100 GB4. On AWS you must rent eight GPUs, and a p4de instance running all month costs about $20,0367.
Most keep charging for storage while an instance is stopped, and the rates differ widely. On GPUBank a stopped machine costs only its persistent disk at $0.03 per GB-month, $6.00 a month for 200 GB1. Runpod charges $0.20 per GB-month for an idle volume disk, twice its running rate, so the same 200 GB left idle for a month costs $40.00, or $14.00 on its network storage5. Vast.ai bills storage for as long as the instance exists, running or stopped, at a rate each host sets, and a stopped Vast instance does not keep its claim on the GPU, so restarting can mean waiting or moving hosts29. On the large clouds, attached block storage and reserved public addresses keep billing while the VM is deallocated, so delete what you do not need before leaving a job overnight.
It depends on the provider, and this is one of the largest real differences between a marketplace and a managed cloud. On GPUBank a launch that fails its health check is not billed, and if a host fails mid-job the machine is restarted on a healthy host with the same disk and the interrupted session is credited in full1. On a peer-to-peer marketplace a host that disappears ends your session, whatever was not checkpointed to storage you control is lost, and whether any time is refunded depends on the platform's rules, which is why Vast.ai publishes a reliability score for each listing4. Spot capacity on any cloud carries the same risk by design in exchange for its lower price. Whatever you rent, write checkpoints to a persistent disk or external storage often enough that a failure costs minutes rather than hours.
Rent, unless you already run a data-centre rack and can keep eight cards busy most of every day for two years. AmCompute valued a used HGX A100 node with eight 80 GB cards at $95,200 in October 2026, and used module prices fell about 35 percent over the year to August3435. Assuming that decline continues, the server is worth about $40,000 after two years, so depreciation costs $2,300 a month, and power at 5 kW and 18.19 cents per kWh adds $0.91 per machine-hour39. That breaks even with GPUBank's $0.95 on-demand rate at about 344 hours per GPU per month, with its $0.76 reserved rate at 445 hours and with its $0.59 effective rate at 599 hours, before rack space, cooling, networking, spares and staff time, which all push the break-even higher.
A used A100 SXM4 80 GB module sold for about $4,700 to $5,400 over the twelve months to August 2026 according to AmCompute's appraisal of realised sales, down about 35 percent on the year before35. Asking prices are higher and scattered: Caladan Semi recorded US asks of $8,300 to $12,200 with a median of $9,925 on 9 September 2026, from only four listings, and Jarvislabs' guide gives $5,000 to $9,000 used and $10,000 to $15,000 new3637. The 80 GB PCIe card asks more, a median of $18,500 in Caladan's data, because it fits ordinary servers, whereas an SXM module needs an HGX baseboard. A whole used eight-GPU HGX A100 node was valued at $95,200 by AmCompute and $80,000 to $120,000 for a used DGX A100 by Jarvislabs3437.
Yes, on GPUBank crypto is the only way to pay for now: you top up a prepaid US dollar balance with Bitcoin, Ethereum, USDT, USDC, Monero or more than a dozen other coins, from $25 to $5,000 at a time, and cards are not accepted1. The balance never expires, and each top-up carries a bonus of 20 percent from $25, 30 percent from $50, 35 percent from $100, 40 percent from $250, 50 percent from $500 and 60 percent from $1,000, which brings the A100 SXM's $0.95 on-demand hour to about $0.79, $0.70 and $0.59 at the $25, $100 and $1,000 levels. Every account and every team member can have a monthly spend cap. The bonus is worth having only on credit you will actually spend, because the money is committed up front. A team that must pay by card should look at CloudRift, Thunder Compute or Runpod, the nearest managed offers on price235. GPUBank is run by GPU Compute OÜ in Tallinn, Estonia, registry code 17984370.
Sources
Sources
- 01GPUBank pricingGPUBank A100 SXM rates in three modes, inclusions, disk price, billing rules, top-up bonuses, other cards · read 16 Oct 2026
- 02CloudRift pricingA100 SXM4 on demand, one-month and three-month rates, 800 GB storage · read 16 Oct 2026
- 03Thunder Compute pricingA100 80GB rate, included machine, per-minute billing, reserved rate · read 16 Oct 2026
- 04Vast.ai live offers API, A100 SXM4 searchLive 80 GB offers, on-demand prices, minimum bids, storage and bandwidth rates · read 16 Oct 2026
- 05Runpod pricing (updated 8 Oct 2026)Secure Cloud, Community and Serverless A100 rates, storage prices · read 16 Oct 2026
- 06Lambda pricing8x A100 SXM 80 GB instance, single-GPU A100 40 GB · read 16 Oct 2026
- 07Vantage, p4de.24xlargeAWS on-demand, spot and reserved prices (aggregator) · read 16 Oct 2026
- 08gcloud-compute.com, a2-ultragpu-1g and 8g (11 Oct 2026)Google Cloud on-demand and spot prices (aggregator) · read 16 Oct 2026
- 09GetDeploying, Nvidia A100 rental pricesMarket median across 39 priced providers, 15 Oct 2026 · read 16 Oct 2026
- 10NVIDIA A100 Tensor Core GPUSpecifications · read 16 Oct 2026
- 11AWS, EC2 P4 instancesp4d and p4de specifications · read 16 Oct 2026
- 12Jarvislabs pricingA100 80GB rate and machine · read 16 Oct 2026
- 13Koyeb pricingA100 80GB and A100 SXM serverless rates · read 16 Oct 2026
- 14Modal pricingA100 80 GB per-second rate · read 16 Oct 2026
- 15Dettmers et al., QLoRA (arXiv 2305.14314)65B model fine-tuned on a single 48 GB GPU · read 16 Oct 2026
- 16Beam pricingA100 80 GB SXM4 machine from $1.36 · read 16 Oct 2026
- 17Massed Compute pricingA100 SXM4 80 GB, 1 and 8 GPUs · read 16 Oct 2026
- 18Hyperstack, A100 SXMOn-demand and reserved rates · read 16 Oct 2026
- 19Verda GPU instancesA100 SXM4 80GB rate and machine · read 16 Oct 2026
- 20Azure Retail Prices API, Standard_ND96amsr_A100_v4, eastusPay-as-you-go, spot and reservation prices · read 16 Oct 2026
- 21Crusoe pricingA100 80GB SXM and PCIe rates · read 16 Oct 2026
- 22Vast.ai, Rent A100 SXM4 GPUsStatic page showing no current offers · read 16 Oct 2026
- 23Lium, A100Reference price, no pod available · read 16 Oct 2026
- 24Thunder Compute, NVIDIA A100 pricing (reviewed 9 Oct 2026)Vast.ai A100 80 GB median $1.63 over three hosts ($1.21 to $1.76); Paperspace $3.18; CoreWeave $2.70 per GPU · read 15 Oct 2026
- 25TensorDock, A100On-demand and spot starting prices, host locations · read 16 Oct 2026
- 26AWS News Blog, price reduction for NVIDIA GPU instances (5 Jun 2025)June 2025 price cut · read 16 Oct 2026
- 27AWS P4 page, Wayback Machine, 5 Aug 2022p4de.24xlarge at $40.96 an hour in 2022 · read 16 Oct 2026
- 28Economize, OCI BM.GPU.A100 (8 Oct 2026)Oracle bare-metal A100 price (aggregator) · read 16 Oct 2026
- 29Vast.ai documentation, BillingStorage billed while stopped, bandwidth per byte · read 15 Oct 2026
- 30MLCommons, MLPerf Training v2.1 results (NVIDIA run logs)BERT and ResNet-50 time to train, DGX A100 80 GB and DGX H100 · read 16 Oct 2026
- 31EE Times, Nvidia shows off Hopper MLPerf training benchmarks (29 Nov 2022)BERT 6.4 min on 8x H100, 16.8 and 28.2 min on 8x A100 · read 16 Oct 2026
- 32NVIDIA Technical Blog, Leading MLPerf Training 2.1 (9 Nov 2022)FP8 Transformer Engine in the H100 BERT submission · read 16 Oct 2026
- 33E2E Networks, TIR inference benchmarks (updated 15 May 2026)Llama 3.1 8B TensorRT-LLM throughput, A100 and H100 · read 16 Oct 2026
- 34AmCompute, A100 vs H100Used HGX A100 8x 80 GB node valuation · read 16 Oct 2026
- 35AmCompute, A100 SXM4 80GB appraisalRealised used sale prices to August 2026 · read 16 Oct 2026
- 36Caladan Semi, used H100 and A100 buying guide 2026US asking prices on 9 Sep 2026 · read 16 Oct 2026
- 37Jarvislabs, NVIDIA A100 price in 2026New and used module and DGX prices · read 16 Oct 2026
- 38NVIDIA DGX A100 datasheet (Colfax copy)6.5 kW maximum system power · read 16 Oct 2026
- 39EIA, Electric Power Monthly, table 5.3US average electricity price used in the buy calculation · read 15 Oct 2026
- 40Lambda GPU cloud, Wayback Machine, 12 May 20238x A100 80 GB at $1.50 per GPU · read 16 Oct 2026
- 41Lambda GPU cloud, Wayback Machine, 16 Mar 20258x A100 SXM 80 GB at $1.79 per GPU · read 16 Oct 2026
- 42Runpod pricing, Wayback Machine, 9 Jul 2023A100 SXM 80 GB at $1.84 · read 16 Oct 2026
- 43Runpod pricing, Wayback Machine, 13 Jun 2024A100 SXM 80 GB at $2.29 · read 16 Oct 2026
- 44CNBC, Nvidia's A100 is the $10,000 chip powering the race for AI (23 Feb 2023)New price around $10,000 · read 16 Oct 2026
- 45NVIDIA press release, DGX A100 (14 May 2020)DGX A100 from $199,000 · read 16 Oct 2026
What we could not confirm
Several figures rest on aggregators because the provider's own page could not be read: AWS prices come from Vantage (the region of its default view is not shown, and AWS's page no longer lists prices), Google Cloud from gcloud-compute.com and Oracle from Economize, since Google's price tables did not render and Oracle refused our requests. Vast.ai's public price page showed no offers and a blank headline, so its figures come from the live offers API at one moment on 16 October, and marketplace prices move by the hour. Runpod's Community Cloud A100 SXM at $1.39 appears only in the page's structured data, Crusoe's page did not make clear whether $2.30 is the on-demand column, TensorDock's page quotes three different starting prices, and Lium had no pod to price. Jarvislabs no longer shows the $0.89 spot A100 the research pass reported, Thunder Compute shows no $0.79 tile, and Verda's spot A100 price is not displayed. The MLPerf minutes were computed from MLCommons run logs with the MLPerf scoring rule and match EE Times for BERT, but EE Times gives 28.2 rather than 28.69 minutes for the closest 8x A100 ResNet-50 score; E2E's benchmark page does not state precision, software version or form factor, and Microsoft's Azure vLLM benchmark could not be read. eBay listings for used modules and servers returned errors, so purchase prices rest on AmCompute, Caladan Semi and Jarvislabs; the 35 percent annual decline, the 5 kW draw and the electricity price in the buy calculation are assumptions. We found no measured comparison of the A100 SXM with the L40S, the RTX PRO 6000 or the H100 PCIe on a common test, and could not recheck the September figures for LeaderGPU, Prime Intellect, io.net, Denvr, Gcore, Oblivus, Spheron, Civo, E2E Networks, Vultr, OVHcloud, Paperspace, CoreWeave, Akash and Clore.ai, which are therefore left out.
A100 SXM on GPUBank
Eighty gigabytes of Ampere, billed by the second.
- 16 vCPU, 125 GB RAM, 1 TB NVMe, IPv4 and traffic in $0.95/hr
- Billed by the second after the health check
- Interruptible $0.57, reserved $0.76
 16 vCPU, 125 GB RAM, 1 TB NVMe, IPv4 and traffic in $0.95/hr
More GPU price guides
Where to rent the other cards at the cheapest price.
 B200 SXM180 GB HBM3eFrom $2.49 spot · $4.15 all-in
 H200 SXM141 GB HBM3eFrom $1.49 spot · $2.49 all-inH100 SXM80 GB HBM3From $1.11 spot · $1.85 all-inH100 PCIe80 GB HBM2eFrom $0.81 spot · $1.35 all-in
 MI300X192 GB HBM3From $0.99 spot · $1.65 all-inRTX PRO 600096 GB GDDR7 ECCFrom $0.69 spot · $1.15 all-inL40S48 GB GDDR6 ECCFrom $0.33 spot · $0.55 all-in
 RTX 509032 GB GDDR7From $0.29 spot · $0.48 all-in
 RTX 409024 GB GDDR6XFrom $0.14 spot · $0.23 all-in